Connections and models
Connect Grounded to OpenAI-compatible gateways, add chat, embedding, moderation, SystemOne and vision models, and set their classification ceilings.
Grounded has no built-in model provider. Platform admins connect it to one or more OpenAI-compatible gateways (LiteLLM, vLLM, SGLang, a hosted API, or anything that speaks the OpenAI API) and add the models teams may use. Nothing is added automatically.
Connections
Models → Connections → Add connection:
| Field | Meaning |
|---|---|
| Name | Shown in model lists and used as the connection label in metrics. |
| Base URL | The gateway's API root, including /v1, for example https://gateway.example.org/v1. Admins may point it at private addresses; the crawler's address rules don't apply here. |
| API key | Stored encrypted with ENCRYPTION_KEY (AES-256-GCM). The API never returns it; the page only shows that one is set. |
| Timeout | Per request. |
| Requests per minute | Optional. Enforced across every Grounded process. Set it just below your gateway key's limit (for example 110 for a key allowed 120). Without it, bulk work sends requests as fast as the gateway answers. |
| Maximum concurrent requests | Default 8, per process. Applies to SystemOne calls, since a GPU serves few at once. |
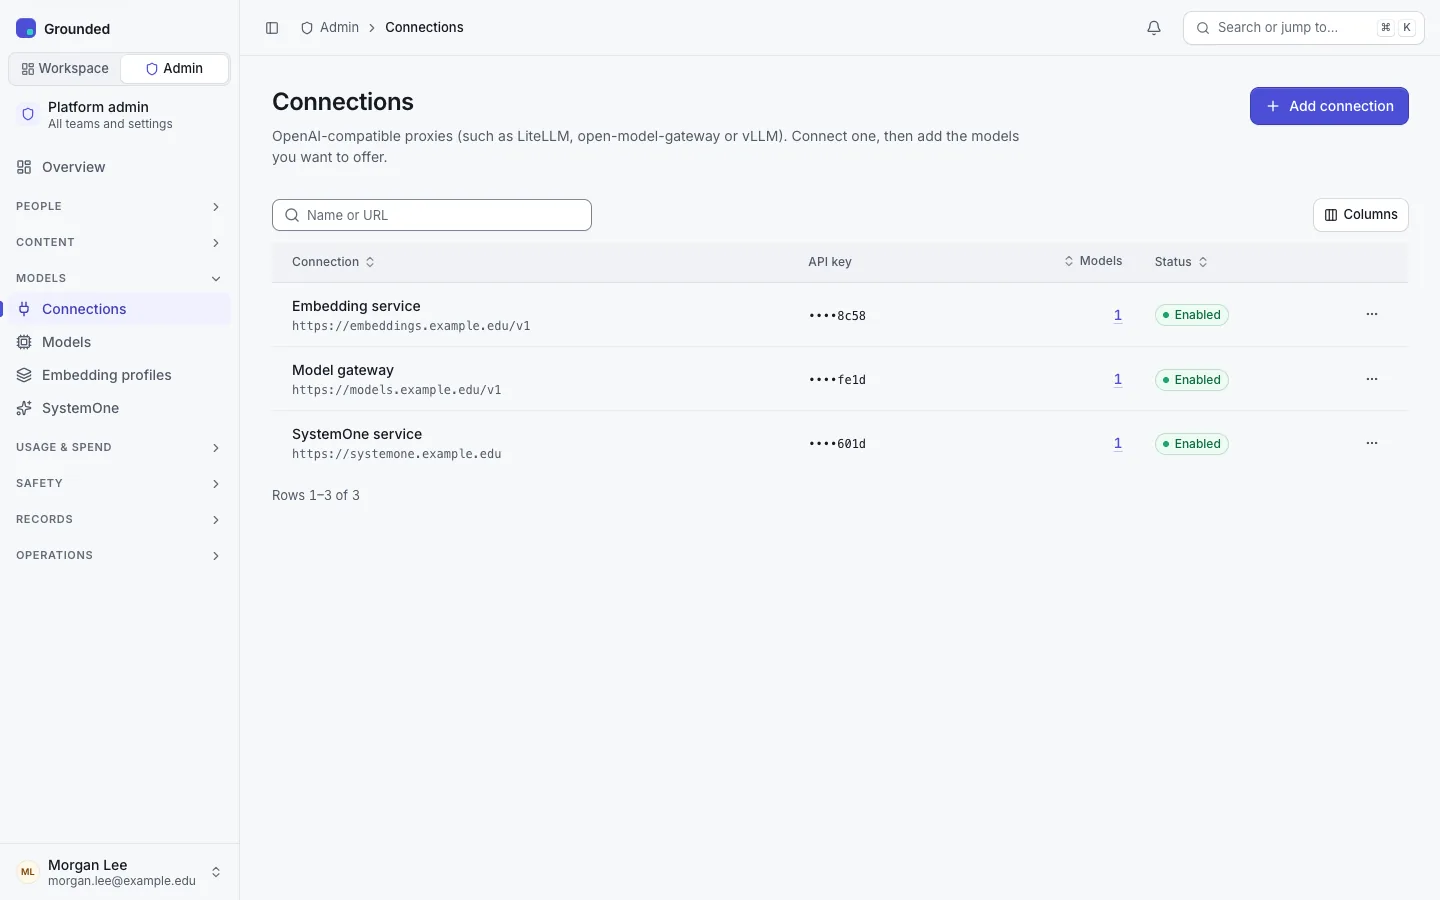
Test connection calls GET /models and lists the gateway's model IDs to help you fill in the model form. It reports timings for each phase (DNS, connect, TLS, first byte) and names the cause of a failure, such as an untrusted certificate or a refused connection.
Grounded uses only the OpenAI API surface (/models, /embeddings, /chat/completions, and /moderations for moderation endpoints) plus POST /v1/systemone for SystemOne models. It has no vendor-specific code.
Models
Models → Models → Add model adds one model from a connection:
- Upstream model ID: what the gateway calls it. Display name: what people see.
- Kind: Chat, Embedding, Moderation, SystemOne or Vision (OCR). (
rerankis reserved for a future reranker and isn't used yet.) - Maximum classification: the most sensitive level this model may process. Which models may take Restricted data is your organisation's policy, commonly self-hosted models or services under a data agreement. Tag each model as you add it.
- Kind-specific capabilities: for chat, the context window, maximum output tokens, tool calling and vision; for embeddings, the dimensions and maximum input tokens.
- Enabled: a disabled model stops being offered and used.
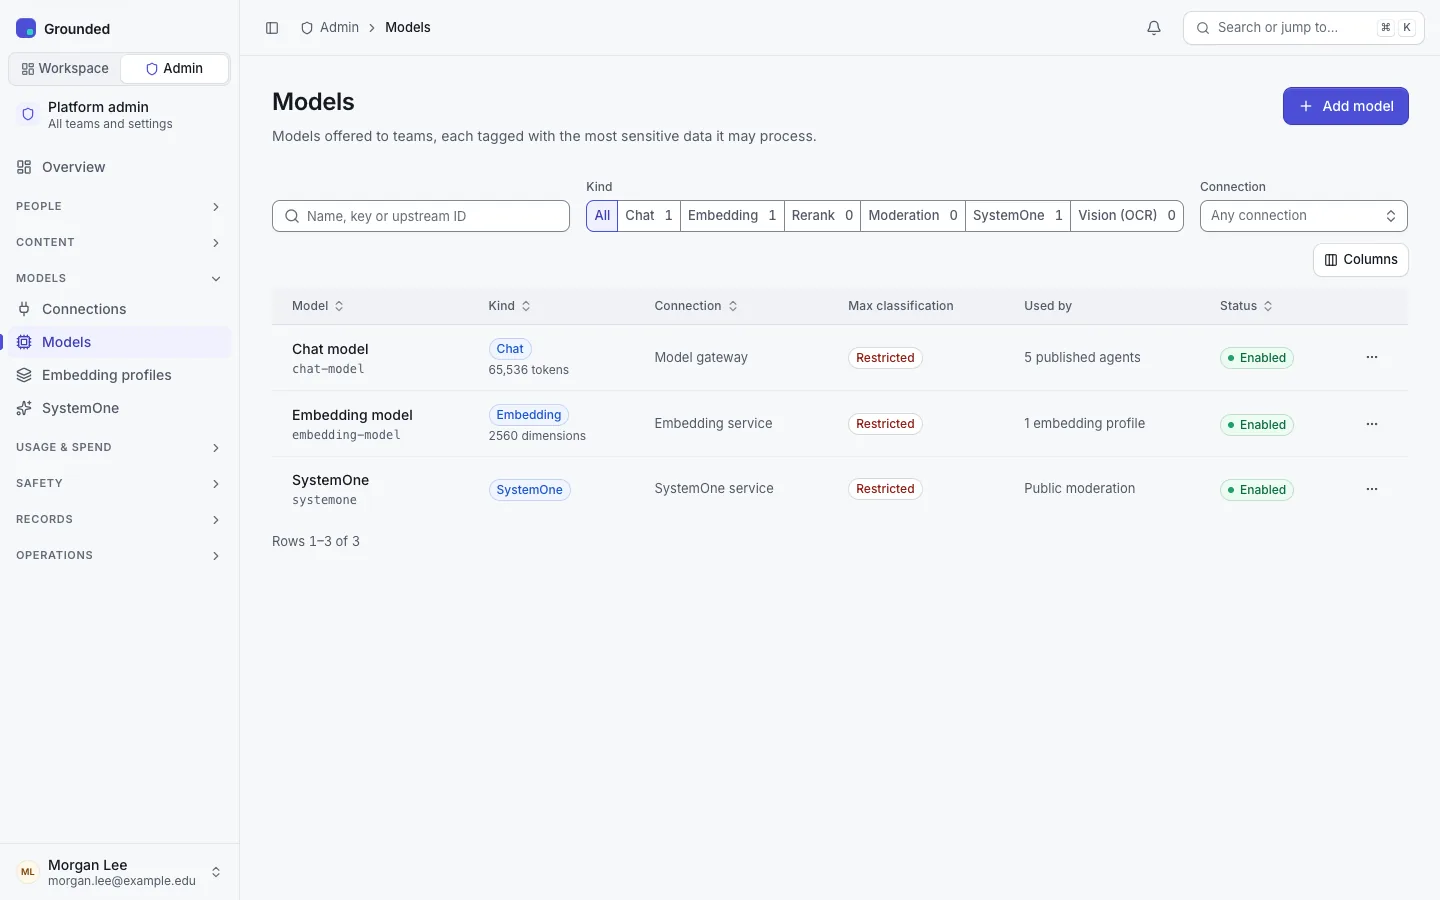
Test model sends a tiny real request: a one-word chat completion, an embedding of a short string (it reports the dimensions the gateway actually returns), a benign and a harmful sample for moderation, or the built-in sample page for a vision model.
Compatibility
Gateways differ in small ways. A model's Compatibility section adjusts what Grounded sends:
| Flag | Kind | Default | Effect |
|---|---|---|---|
| Developer role | chat | off | Send the system prompt with role developer instead of system. SGLang rejects developer. |
| Reasoning effort | chat | off | Send the agent's reasoning_effort. Unknown fields break some gateways. |
| Stream usage | chat | on | Ask for usage in the last streamed chunk. |
| Max tokens field | chat | max_tokens | max_tokens or max_completion_tokens. |
| Tool choice | chat | off | Send tool_choice, only for servers that honour it. |
| Thinking field | chat | either | The streamed reasoning field: reasoning_content or reasoning; empty reads whichever is present. |
| Extra body | chat, moderation | none | A JSON object (at most 4,096 bytes) merged into every request, for server extensions, for example {"chat_template_kwargs": {"enable_thinking": false}}. It can't override the fields Grounded controls. |
| Dimensions parameter | embedding | off | For profiles with output dimensions: send the OpenAI dimensions parameter. When off, Grounded shortens and renormalises the vectors itself. |
Model gateways has recipes for self-hosted servers.
Pricing
A model's Pricing section holds its dated prices, used by cost tracking. Prices are never edited: a change adds a row effective from a date. You can enter prices before turning cost tracking on.
Classification ceilings in practice
The maximum classification is enforced everywhere, when anything changes and again on every question:
- A source's embedding profile inherits its model's ceiling; a source can't be classified above it.
- An agent's chat model must be approved for its most sensitive knowledge base.
- A moderation or SystemOne model sees the question, and for citation checks the passages; its ceiling applies too.
- A vision model only reads scans from sources at or below its ceiling.
Every question checks the published agent's model and data against the current ceilings. If you lower a model's ceiling below data it already serves, the agents affected are refused at their next question rather than quietly degraded, so check what uses a model before you lower it. An embedding model that a profile uses can't change its upstream model or dimensions: add a new model and profile instead.
When the gateway is down
Chat and search return a clear "model unavailable" error. Admin pages, document management and queued ingestion keep working, and embedding work waits and retries. A gateway's 429 or 503 with Retry-After is treated as back-pressure: work pauses and continues, and every Grounded process backs off. The alerts include a failing or rate-limited connection.